
How to Build a GEO Strategy from Scratch: 2026 Playbook
How to build a GEO strategy from scratch: a 50-prompt baseline, topic clusters by inclusion rate, off-domain authority and a 90-day plan to track AI citations.
In short: Build a GEO strategy in four steps. Run a baseline of about 50 prompts per country, mostly non-branded. Map topic clusters by how often the brand is included in AI answers. Build off-domain authority through reviews, communities and earned media. Then rerun the same prompts after 90 days and track citation share, not traffic alone.
Most growth teams are in the same spot right now. Organic traffic still matters, paid is still doing heavy lifting, and yet buyers are increasingly getting their first answer from a generative system before they ever hit a website. The result is awkward and very real, because the brand can be present in search, invisible in the answer layer, and still lose the deal before the click ever happens.
This playbook is written by the team at Sprints & Sneakers, a growth marketing agency in Amsterdam that runs generative engine optimization (GEO) programs for B2B and B2C brands. If you are new to the term, start with what generative engine optimization is.
That is why how to build a GEO strategy from scratch is no longer a niche topic. It's the practical question behind whether a brand gets cited, recommended, or skipped when someone asks a high-intent prompt. The old habit of chasing blue links still has value, but it doesn't tell a team whether AI systems trust the brand enough to include it in the conversation.
For teams already thinking in full-funnel terms, the mental model shifts fast. GEO sits upstream of the website in a way traditional SEO never did, and the buyer journey now has a pre-funnel layer where models decide which names enter consideration at all. For a useful contrast with classic funnel thinking, the full-funnel framing at Sprints & Sneakers shows why this new layer matters to pipeline, not just to visibility.
The good news is that the work is operational, not mystical. A strong GEO program starts with a tight baseline, then expands into topic gaps, off-domain authority, and a measurement system that stays small enough to use. The temptation is to treat it like another content project. That usually wastes the first quarter.
Table of Contents
- The Funnel Has Moved and Your SEO Playbook Will Not Save You
- Run a Tight 50-Prompt Baseline Before You Touch Any Content
- What Good Looks Like With Citations and Qualified AI Traffic
- Map Topic Clusters by Share of Inclusion Rate
- Off-Domain Authority Beats Schema Markup Every Time
- The 10-15 Buyer-Intent Query Workflow for a Three-Month Validation
- Your First 90 Days, Your Metrics Board, Your Next Move
The Funnel Has Moved and Your SEO Playbook Will Not Save You
The easiest way to see the shift is to watch a normal buying moment. A marketing lead asks a generative system which supplier is worth shortlisting, and the brand with the best page title doesn't always win. The answer set is built before the website visit, which means the old playbook can still generate impressions while the model recommends someone else.
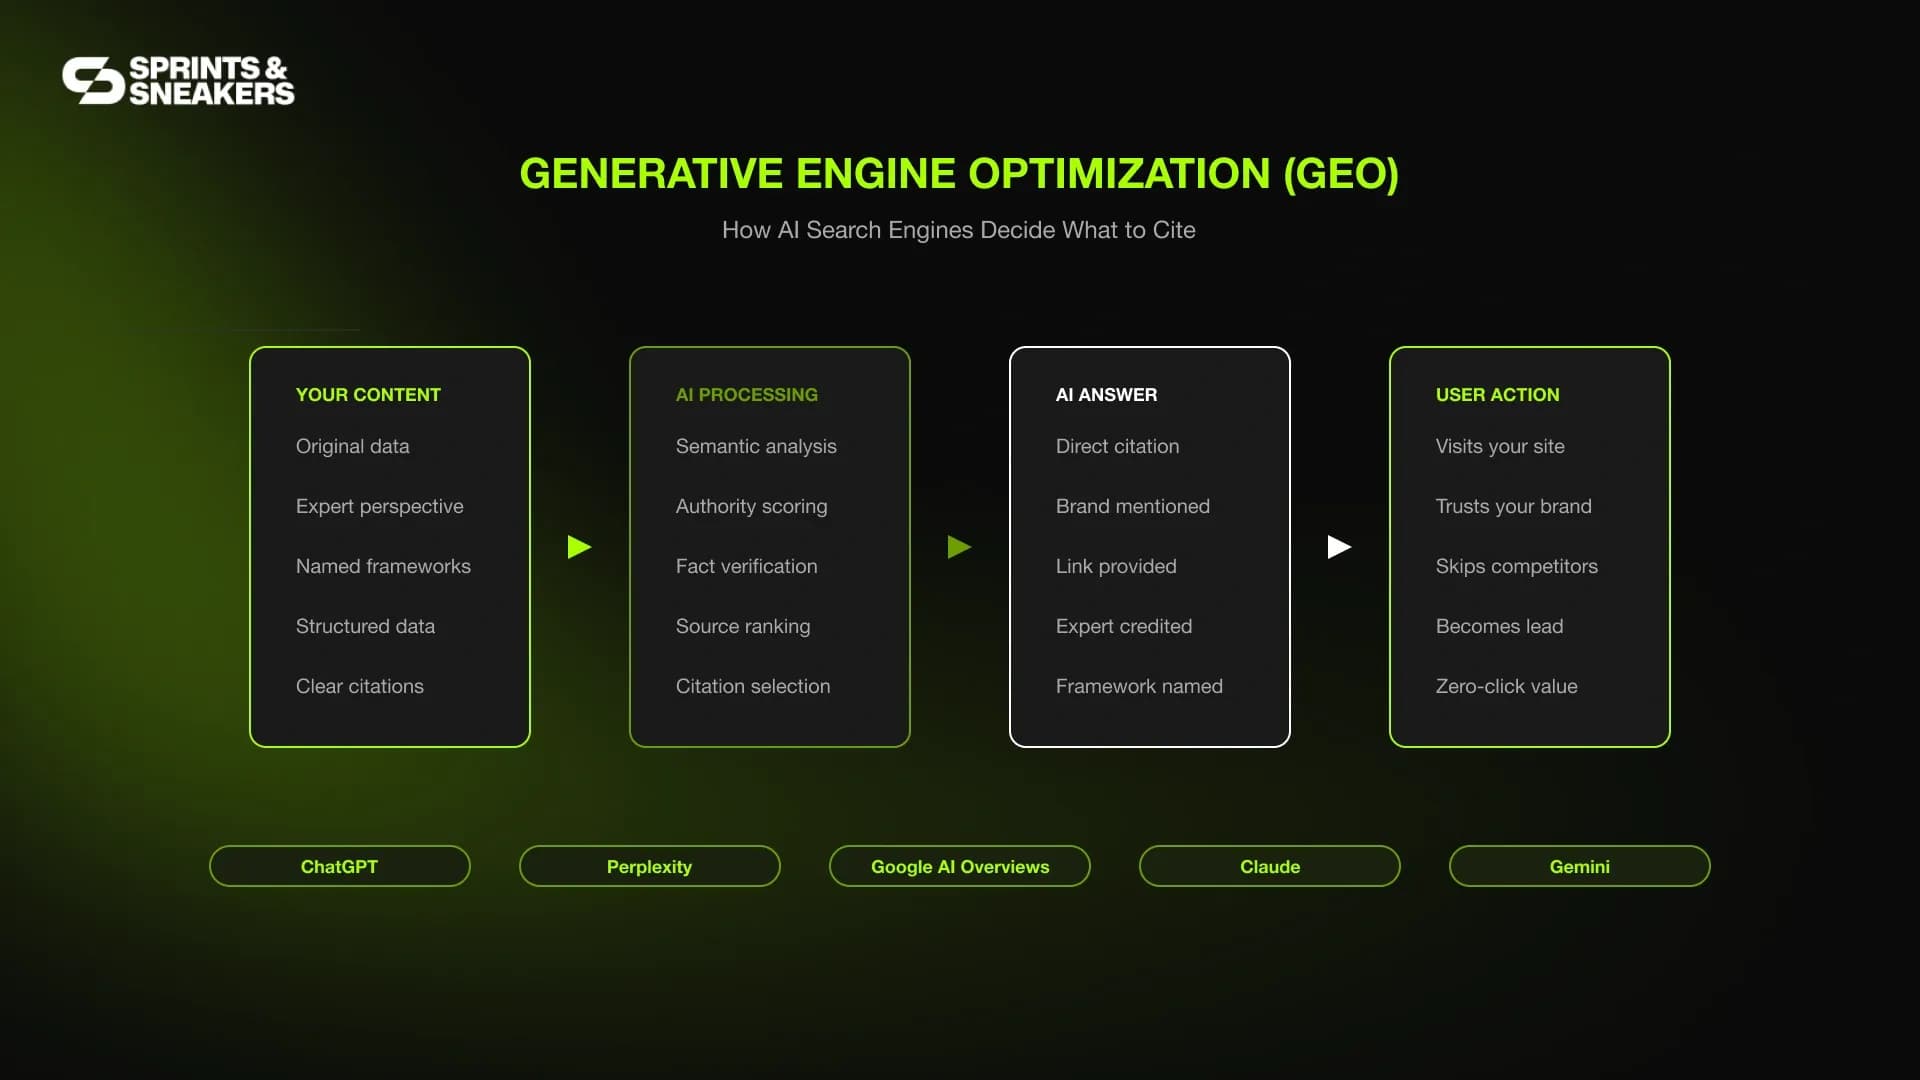
That is where GEO changes the game. Traditional SEO focuses on the page, the keyword, and the rank position. GEO asks a harsher question, whether the brand is cited or recommended inside the answer itself, which is a different milestone and a different failure mode.
Practical rule: if the answer engine is deciding who gets into the buyer's shortlist, then traffic is already a downstream metric.
This is also why the dashboard mismatch creates so much confusion. A team can see stable organic sessions and still be losing relevance in generative interfaces. The growth problem is no longer only “how do we get clicked,” it's “how do we get named before the click even exists?”
For a local business, the same logic shows up in a narrower form: discovery already happens inside answer surfaces such as the map pack, not just on pages. GEO extends that thinking into broader prompts, where the brand has to earn inclusion, not just indexation.
The milestone that matters in 2026 is not page rank alone, it's proof that AI systems can retrieve the brand and recommend it with confidence.
That is why the first deliverable should never be a content calendar. It should be evidence that the brand is even present in the answer layer. Once that's visible, the next questions become obvious, which pages influence the answer, which third-party sources reinforce it, and which topics are missing entirely.
Run a Tight 50-Prompt Baseline Before You Touch Any Content
A useful GEO audit starts smaller than many teams expect. A practical first pass is about 50 prompts per country, with an 80% non-branded / 20% branded split so the sample reflects how buyers ask questions in generative interfaces. That keeps the baseline close to real demand instead of filling it with vanity queries that never show up in a buying cycle [source].
Build the prompt set from the category, not from the sitemap
Start with the category, then work outward. Pick the five to ten topics that define the market, then write prompts that sound like commercial questions a buyer would ask, not internal jargon from a content brief. A prompt set built around buyer intent exposes gaps faster, because models respond to the questions people ask, not the way a site is organized.
Use a spreadsheet with these fields:
- Prompt text.
- Brand present or absent.
- What the model says about the brand.
- Who else gets cited.
- Whether the answer feels favorable, neutral, or weak.
Keep the first pass tight. Four measures are enough to start: brand visibility, mention share, sentiment, and the competitive visibility gap. Overtracking slows execution, and those four tell a leadership team whether the problem is visibility, positioning, or trust, without turning the audit into a reporting exercise.

For teams that need a local lens as well, the same audit discipline prevents blind spots: measure what matters first, then widen the scope only after the baseline is honest.
Keep the first week narrow. A small prompt set that gets reviewed properly beats a huge prompt set that nobody trusts.
The mistake is building dashboards before the strategy is validated. That usually creates activity, not clarity. If the initial baseline is thin, fix the sample before adding more charts.
For a broader operational view, the internal playbook on how to use AI in marketing is a useful companion because it reinforces the same discipline, use AI to speed up the work, not to replace the measurement logic.
What Good Looks Like With Citations and Qualified AI Traffic
A GEO roadmap needs a target leadership can read without translation. Citation share, the share of priority prompts in which the brand is cited or named, is the first honest KPI for a CMO, because it shows whether the brand is getting into the answer set at all.
Track AI referral traffic and the leads it brings in as a separate line. Visitors who arrive from an AI answer have already been filtered for relevance by the system, so their quality is worth measuring on its own. That changes the budget conversation: GEO stops looking like branding theatre and starts looking like a channel that shapes downstream intent.
Use the benchmark to set a sane 90-day target
For B2B, the first 90-day goal is usually not volume. It is moving from “rarely cited” to “consistently included on a meaningful slice of priority prompts.” For B2C, the same logic holds, but the focus tends to be on category prompts, comparison prompts, and purchase-adjacent prompts where recommendation language matters.
| Channel | Primary Objective | Leading Indicator | Typical Time-to-Signal |
|---|---|---|---|
| GEO | Get cited or recommended in generative answers | Citation share, mention quality, inclusion in answer sets | Weeks to months |
| SEO | Win search visibility on indexed pages | Rankings, impressions, clicks | Weeks to months |
| Paid Media | Buy immediate demand capture | CTR, conversion rate, cost per acquisition | Days to weeks |
That comparison matters because each channel plays a different role. GEO does not replace SEO or paid. It protects and expands the moment when buyers first encounter the brand in answer systems, and that needs its own measurement board. If you want a clean framing for that board, the definition of marketing analytics is the right companion, because the point is not collecting data, it is choosing which signals change behavior.
A GEO program without a citation-share target turns into a content habit, not a growth system.
A citation share near zero on your priority prompts should be treated as a warning, not a nuance.
Map Topic Clusters by Share of Inclusion Rate
A strong GEO rollout starts with the ugly part: a prompt set that shows where the brand gets left out and where it gets cited without the context you want. Build a 200-500 prompt set across core topics, comparisons, and buyer questions, then measure share of inclusion rate, or SIR, across the AI engines you care about. The gaps that matter most are the clusters sitting at 0% or clearly behind the brands that keep showing up.
Rank clusters by gap severity, not by content volume
Page count usually sends teams in the wrong direction. Exposure is what matters. The useful map is the one that shows which topic clusters are underrepresented in answer systems, because those are the clusters where one solid content brief or one credible authority push can move inclusion faster than publishing another generic article.
A practical workflow looks like this:
- Group prompts by intent: Separate category, comparison, and solution prompts so the signal stays clean.
- Measure inclusion by engine: Record whether the brand appears in each answer set and whether the mention is direct or hedged.
- Compare against peers: Rank clusters by the gap between the brand's SIR and the SIR of the names that keep getting cited.
- Choose the fix type: Decide whether the cluster needs a stronger content asset, off-domain proof, or both.
That last step is where the work gets real. Some clusters are content problems, because the brand does not explain the topic clearly enough for retrieval. Others are trust problems, because the page is fine but the model still wants confirmation from outside the site before it includes the brand. The brief changes based on which one you are dealing with, and so does the budget.
The internal segmentation resource at market segmentation strategy fits this process because GEO clusters should mirror audience segments, not internal org charts. A cluster tied to one buyer group usually needs its own proof points, wording, and references.
The teams that do this well stop treating every gap the same. They write for retrieval when the content is weak, tighten entity language when the brand looks fuzzy, and build supporting references on purpose when the model keeps preferring outside sources. The value comes from earning the kind of mention the system is willing to reuse, not from hoping the page alone will carry the whole job.
Off-Domain Authority Beats Schema Markup Every Time
Most GEO advice overweights tidy on-page fixes. Schema still has a role, but generative systems also cite external sources, community discussions, reviews, and media mentions, so authority is spread across the web, not trapped inside the site. Teams miss that when they treat GEO like a formatting exercise.
A practical rollout starts where models already trust outside signals. That means founder and expert commentary in professional networks, real discussions in relevant forums, review footprints, and earned media mentions that reinforce entity trust. The site still needs clean structure, but off-domain proof often decides whether the brand gets named at all.
A strong off-domain plan usually includes several distinct signal types, because each one does a different job:
- Founder content: Seed point-of-view content where industry conversations already happen, so the brand becomes easier to quote.
- Review sites: Close the gap between what customers say and what the model repeats by encouraging specific, useful feedback.
- Communities and forums: Answer real questions with practical detail, because generic promotion gets ignored.
- Digital PR: Secure credible mentions that support the brand's position in the category.
- Media coverage: Use third-party validation to strengthen the entity graph around the company and its offers.
AI answers often reference competitors, media, and Reddit-style discussions, which means the web's surrounding conversation matters as much as the company site.
That is also why link earning and link building are not the same thing in GEO. Earned mentions and useful coverage can carry more practical value than decorative placement. Generative search is trying to assemble trustworthy evidence, not just count backlinks.

Deciding where to put that effort is part of the strategy. Start with the outside sources that already show up next to your competitors in AI answers, because those are the ones models treat as corroboration. Our GEO approach starts there for the same reason.
The common mistake is obsessing over page markup while ignoring the wider citation ecosystem. If the model trusts outside mentions more than the page alone, the first-quarter work has to include reputation, community, and media, not just internal optimization.
The 10-15 Buyer-Intent Query Workflow for a Three-Month Validation
A lean pilot works better when the budget is contested or the team is small. In that case, the first research wave should narrow to 10-15 genuine buyer-intent queries. For each one, record whether the brand is mentioned, which competitors are referenced and how the brand is positioned, for example as a leader, a niche specialist or not at all [source]. Rerun the same queries after each optimization cycle to see whether the mention rate changes. That gives leadership a clear validation story without pretending the whole category can be fixed in one sprint.
A realistic three-month cadence
Month one is baseline. The team checks the chosen prompts, records which answers cite the brand, and notes where competitors dominate. Month two is the push, where the most likely pages get tightened and the most obvious off-domain gaps get seeded. Month three is the readout, where the same query set gets rerun and the team decides whether the program deserves to scale.
The reason this works is that it creates a closed loop. The brand is not guessing whether the changes mattered, it is comparing the same prompts before and after the work. That makes the conversation with leadership far easier, because the pilot is tied to actual buyer language instead of abstract content output.

<iframe width="100%" style="aspect-ratio: 16 / 9;" src="https://www.youtube.com/embed/mTJsmT0Tkbs" frameborder="0" allow="autoplay; encrypted-media" allowfullscreen></iframe>Go signal: if the brand starts appearing more often in the same buyer-intent prompts and the model's description becomes sharper or more favorable, the pilot has enough evidence to expand.
A no-go result is still useful. If the brand stays absent after the page work and the off-domain seeding, that usually means the prompt set is right but the entity footprint is too thin. In that case, the next round should focus on authority signals, not on publishing more articles that say the same thing in different words.
Your First 90 Days, Your Metrics Board, Your Next Move
A clean 90-day board fits on one screen and gets discussed in a single sitting. Track the four core measures, then add citation share and any AI-attributed pipeline the team can credibly tie back to the work. Leave the rest for later. The common failure is measurement sprawl, not a lack of data.
Keep the next move obvious
Week one is the baseline. Run the prompt set, then choose the 10-15 or 50-prompt path based on resourcing and how much room the team has to test. Week two is page work, tighten the highest-value pages and close the clearest answer gaps. Week three is off-domain seeding, the kind that supports the prompts you already chose. Week four and beyond is the check-in, rerun the same query set and decide whether the program needs more content, more authority, or a different order of attack.
The trap is easy to spot. Teams chase too many metrics, publish broad content, and leave off-domain seeding for later. The result is a busy quarter with little movement in inclusion, which is why early GEO work has to stay narrow and disciplined.

Want to see how this works with content at scale? The AI SEO Agent handles the page work, and our guide to AI SEO agents explains what that automation can and cannot do.
Related articles
Frequently asked questions
A GEO strategy is a plan to get a brand cited or recommended inside answers from generative systems such as ChatGPT, Gemini, Copilot and Google AI Overviews. It starts with a prompt baseline, maps the topics where the brand is missing, builds content and off-domain proof for those topics and measures citation share over time.
A practical first pass is about 50 prompts per country, with roughly 80% non-branded and 20% branded prompts. A smaller team can start with 10 to 15 genuine buyer-intent queries and expand once the first results are in.
Start small: brand visibility, mention share, sentiment and the competitive visibility gap, plus citation share on priority prompts. Add AI-attributed traffic and pipeline once you can tie them to the work. Too many metrics early on slows the program down.
Plan a three-month validation. Month one is the baseline, month two is page work and off-domain seeding, and month three reruns the same prompts to see whether the brand appears more often and is described more favorably.
SEO focuses on rankings, impressions and clicks on indexed pages. GEO asks whether the brand is named or cited inside the answer itself, before any click. GEO does not replace SEO or paid media; it needs its own targets and its own measurement board.
Schema still helps systems understand a page, but generative systems also rely on outside sources such as reviews, community discussions and media mentions. Off-domain authority often decides whether a brand gets named at all, so it belongs in the first quarter of work.